Medical Image Segmentation Using Vision-Language Models
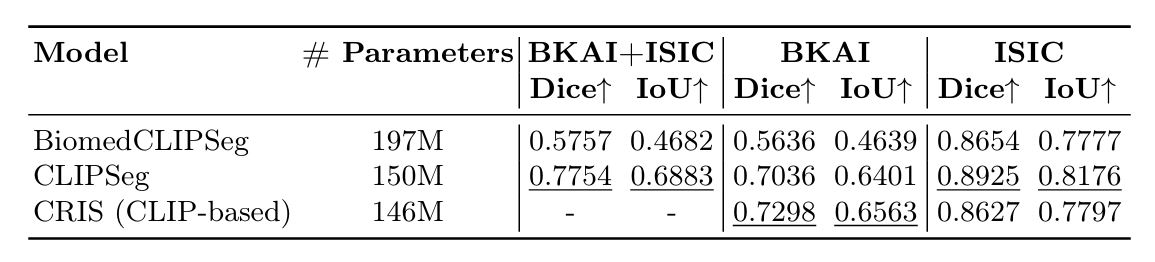
Medical image segmentation is critical for identifying dis- eased regions and aiding physicians in diagnosis. Vision-language models (VLMs) integrate image-text pairs, enabling segmentation tasks guided by textual input and fostering collaboration with domain experts through human-in-the-loop prompting. This study explores transfer learning for medical imaging segmentation, focusing on prompt design and evaluat- ing BiomedCLIP, CLIPSeg, and CRIS models that combine text/image encoders with a segmentation decoder. Qualitative and quantitative anal- yses reveal that suboptimal text embedding often shifts the model’s focus to image features, limiting effectiveness. To address this issue, we propose the text enhancer module, which is expected to enhance text prompts to better balance textual and visual inputs. project slides